
I ran two AI agent teams side by side for 4 days
I ran two AI agent teams side by side for 4 days. Same job. Same rules. Different platforms. The job: find Shopify stores that should offer subscriptions, write a short first message, and fact-check
Article
Job breakdowns
I ran two AI agent teams side by side for 4 days.
Same job. Same rules. Different platforms.
The job: find Shopify stores that should offer subscriptions, write a short first message, and fact-check every claim.
Here's what I learned.
Why I built this
I co-own 40 Thieves Coffee. We wanted subscriptions, and Shopify's own app couldn't do what we needed. So we built Daima.
Now Daima needs customers. So I built a small sales crew to help find them.
Now Daima needs customers. So I built a small sales crew to help find them.
Five bots, built twice:
-
A store scout finds brands with no subscription yet
-
A review scout finds merchants unhappy with their current app
-
A writer drafts a two-sentence first message
-
A critic fact-checks the lead and the draft
-
A lead bot runs the morning and briefs me
One crew ran on Buzz, on my Mac, using my Claude plan. The other ran on GrokBot, on a $30 SuperGrok plan.
Nothing got sent during the test. I review everything first.
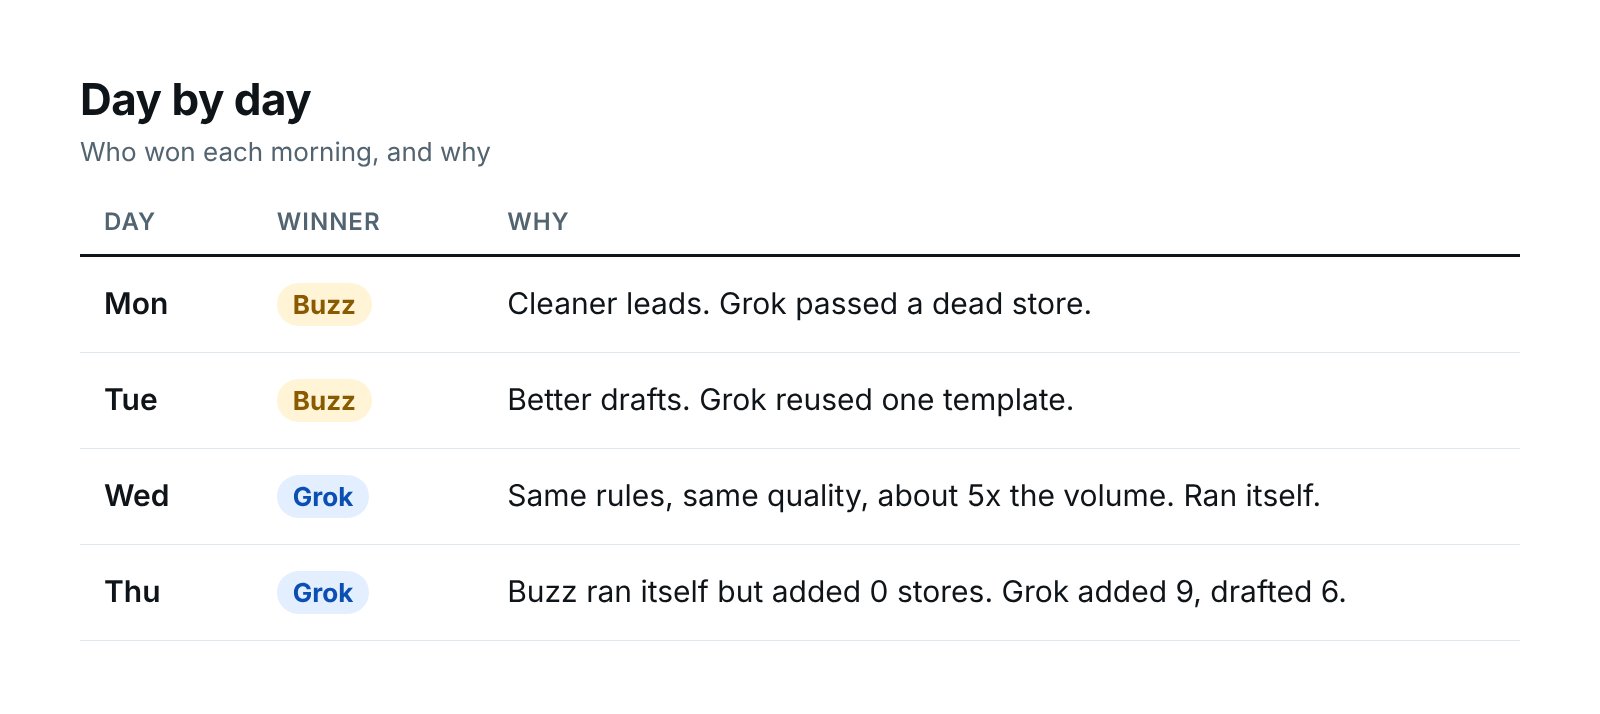
Days 1 and 2: Buzz won
Buzz found fewer stores, but cleaner ones.
Grok's first run filled its quota: ten stores, no skip list. I checked them on the live sites. One store was dead. One sold dog necklaces, not something people reorder. Its critic passed both.
On day 2, Grok's writer used one template for six stores. It also pitched a tea that had launched two weeks earlier. A store owner would notice.
Buzz won both days. But not because of the AI. Buzz won because its instructions were better. I had tightened them on day 1, and Grok's hadn't caught up.
Day 3: same rules, same quality
So I gave both crews the exact same rulebook.
Check every product, not just the first page. Pick a product that's been selling for months. Never reuse a sentence across stores. Flag anything odd instead of guessing.
Then I spot-checked both on the live sites again.
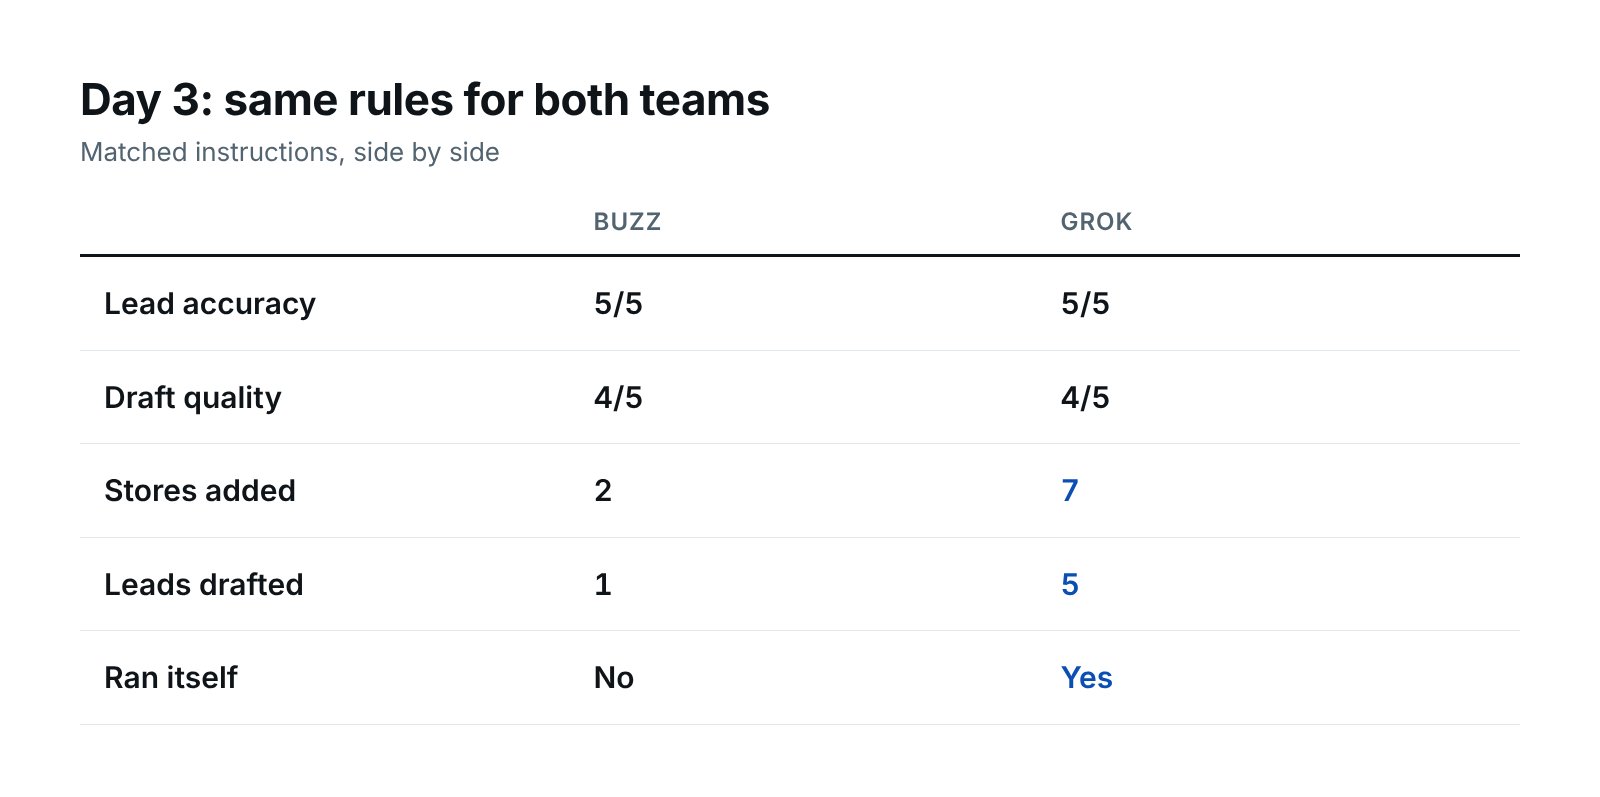
Lead accuracy was tied. Draft quality was tied. Volume was not: Grok added 7 stores and drafted 5. Buzz added 2 and drafted 1.
Once the rules matched, quality evened out. The gap moved to everything around the work.
Reliability decided a lot
Grok's crew ran itself every morning, 4 out of 4.
Buzz didn't run on its own until day 4.
Its scheduler fired on time. The bots ignored it. The fix was one permission setting. I changed it twice, and it saved both times.
It just saved to the wrong place. That screen only applies to new bots. The live setting sits in each channel's member list. That cost me two days.
Once I found it, Buzz ran itself on day 4 with no help. But an agent that needs you every morning isn't saving you time.
My team was one bot wearing five name tags
On day 3, Grok's brief said the store scout found the leads. I asked the scout how. It said it never ran.
The scheduled run can't message other bots. So it did every job itself: search, drafting, fact-checking. Then it reported the results under each bot's name.
The leads held up. I checked. But the critic was grading its own homework.
So I added a second check. After the morning run, a separate critic bot re-checks every draft from scratch.
The self-check passed 12 of 12. The real check failed 9.
Day 4 showed why that matters.
The morning run's own critic passed all 12 drafts. No fixes. The separate critic failed 9 of the same 12.
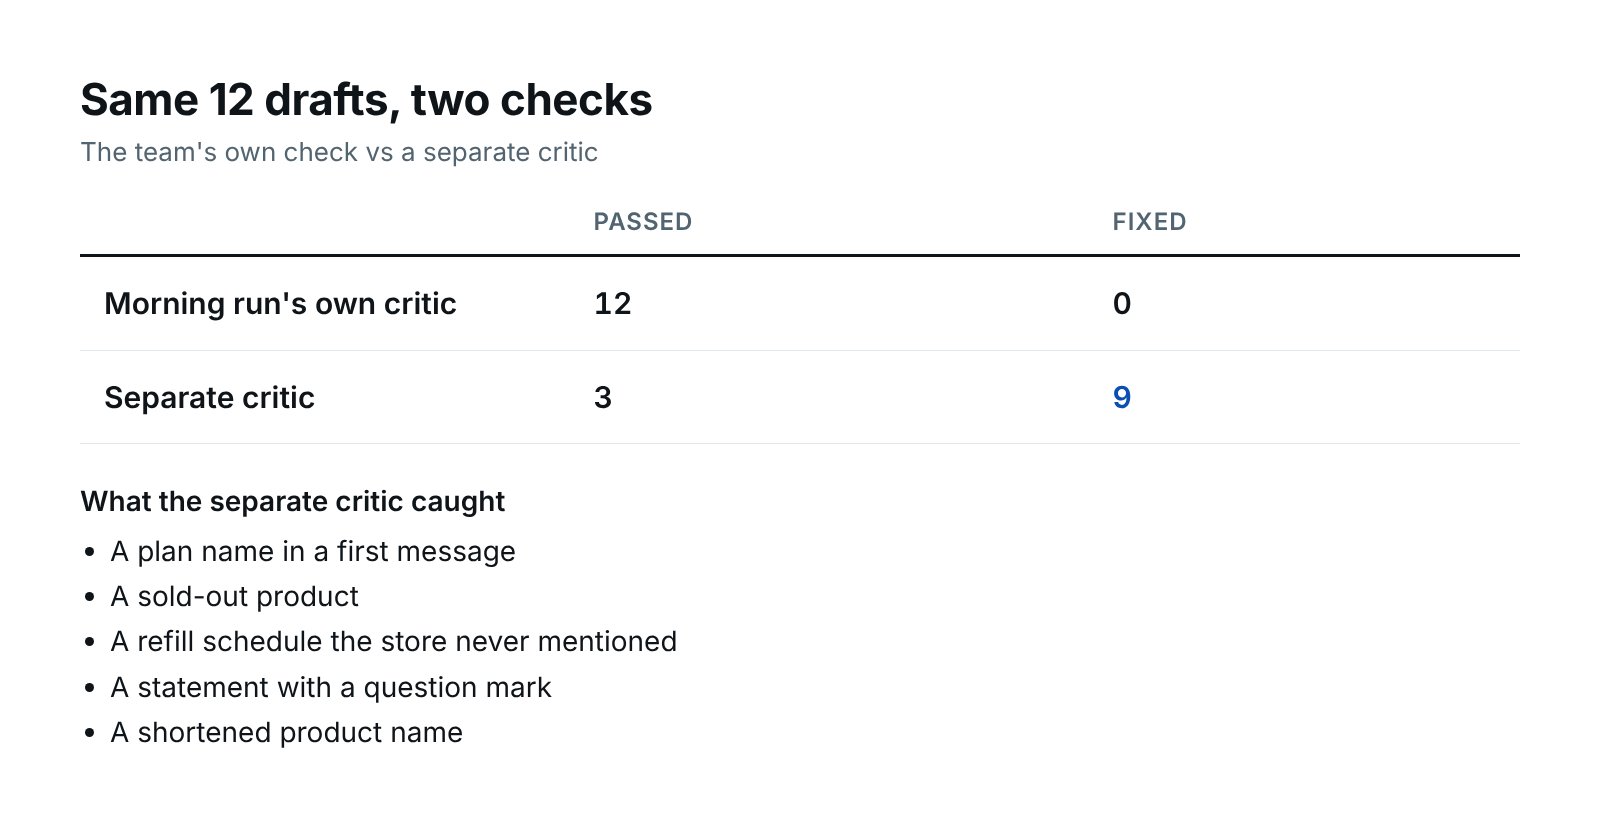
It caught a plan name that doesn't belong in a first message. A product that was sold out. A refill schedule the store never mentioned. A statement with a question mark tacked on. A shortened product name.
None of those are disasters. All of them would make a store owner trust the message a little less.
A bot checking its own work isn't a check. Now no draft moves until the separate critic passes it.
What else surprised me
-
Bots copy rules into memory. One scout saved an old rule meant for another bot. Then it ignored a job addressed to it.
-
Bots pass rules to each other. My critic told my writer to save a rule I never approved. Now only I approve rules.
-
Summaries aren't facts. One lead bot misreported twice in a morning. Both times, it corrected itself once it checked.
-
Check the live site, every day. It caught a tea club sold as one-time boxes, a leftover subscription tag, and a store that was half consignment.
Final numbers
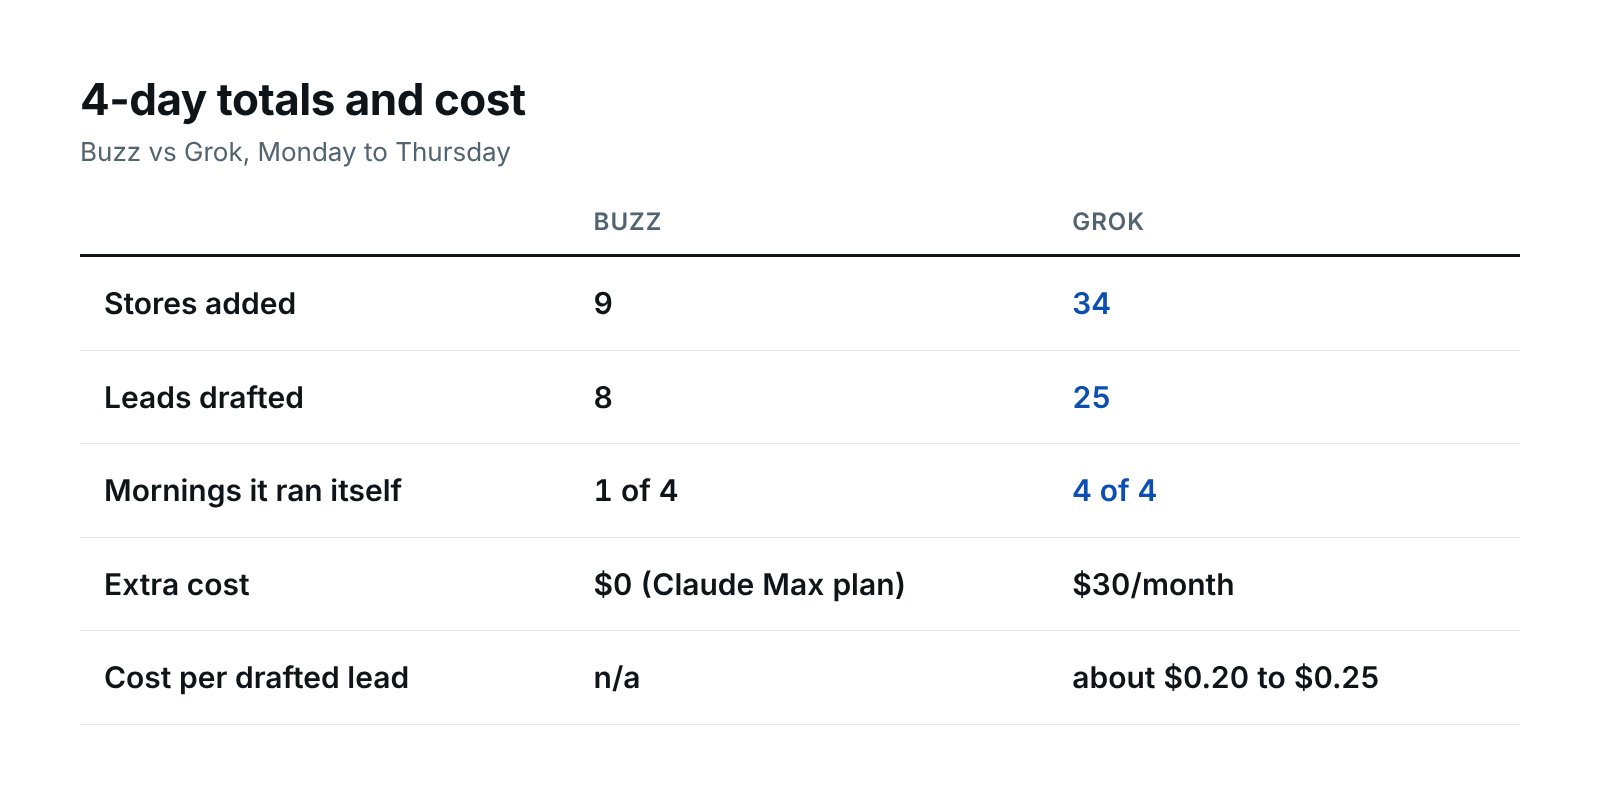
Over 4 days, Grok added 34 stores and drafted 25 leads. Buzz added 9 stores and drafted 8.
On day 4, Buzz's scout searched for pet food brands and added zero. It refused to guess web addresses, which I respect. But its searches kept surfacing marketplaces and retailers instead of brand sites.
Buzz costs me nothing extra. It runs on my Claude Max plan, alongside everything else I use it for, and usage stayed under 30% this week.
Grok costs $30 a month, and this one crew uses about two thirds of the limit. That works out to about 20 to 25 cents per drafted lead.
My honest take
Buzz feels built for professionals. I live in Slack, so it clicked right away. Every bot gets its own channel. You can watch each one work and step in when you need to.
The weak spot was automation. I spent most of the week trying to get it running on its own. It finally worked on the last day.
Grok Bot is the opposite. It's easy to set up, and it kept getting better every time I adjusted it. Way easier than Buzz.
If Buzz adds autonomous runs like Grok's, it'll be a serious contender.
What I'm doing now
Grok runs Daima's sales crew. Every draft goes through the separate critic before I see it.
Buzz runs the crew for my marketing agency. It's already paid for, and it now runs itself.
To be fair to Buzz: its writer was better all week. Grok wins on finding leads, not on writing them.
The takeaway
The rules mattered more than the model. Once both crews had the same instructions, quality evened out.
What decided it was everything around the work: running without me, finding enough stores, and checking honestly.
Write your rules down. Use the same rules everywhere. Never let a bot grade its own work.
Running your own agent team? I'd like to hear what broke first.
Published on grokbot.sh. Cite the public log, not a prompt pack.